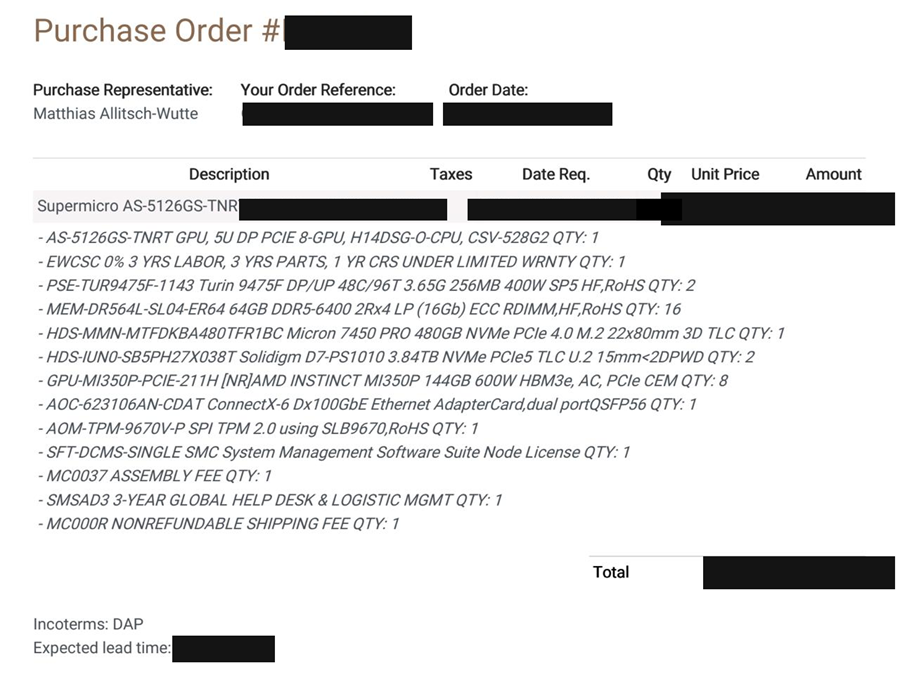
Why we ordered AMD Instinct MI350P GPUs: more memory, a normal data center, fully managed in AT and DE.
Matthias Allitsch-Wutte · GEKI founder
2 September 2026 · 6 min read
Until now, there was no way around NVIDIA for us either. The RTX PRO 6000 (Blackwell) are top GPUs – and still a good choice if you want to stay in the NVIDIA ecosystem. Our first AI factories run on them. For the next ones we have now deliberately ordered AMD – Supermicro servers with 8× AMD Instinct MI350P. Why not NVIDIA as the base this time? Three reasons:
GEKI builds and operates AI factories for inference – for companies that want to use AI regionally and cheaply for their own applications: without hyperscaler supplier risk, without their data in US data centers, with full data sovereignty – but that don’t want to deal with hardware, the inference stack or the data center.
You get OpenAI-compatible API endpoints from us – the convenience of a hyperscaler, only in Austrian and German data centers. You choose the location. We run the AI factory 24/7 and manage models, routing and scaling. You use AI for your applications.
A Supermicro server with 8× AMD Instinct MI350P (144 GB HBM3e each), AMD EPYC CPUs, 1 TB of RAM and fast NVMe storage. That’s 1,152 GB of GPU memory in a single machine.
Modern AI models need one thing above all: a lot of VRAM. Size decides which model can run at all – that was the main reason for AMD. The MI350P also uses HBM3e, not GDDR like the RTX PRO 6000: significantly more bandwidth. Example: DeepSeek V4 Flash (284B parameters) needs about 160 GB just for the weights. It does not run on a single RTX PRO 6000 (96 GB). On two of them (192 GB) it gets too tight for multiple requests at once. With 2× MI350P (288 GB) there is enough headroom.
(More in our VRAM comparison: how much memory Qwen, DeepSeek and Kimi really need.)
We deliberately chose the air-cooled PCIe variant (MI350P). Each GPU draws about 600 W – so the whole server runs in a normal data center rack, with no special liquid cooling and no hyperscaler site required. That’s exactly why we can offer more regional locations.
That’s our point: we build AI factories for mid-market companies that want sovereign AI – near peak quality with open models, but without a hyperscaler data center. The hardware sits where your data should be: in an Austrian or German data center – you choose the location.
The models our customers run change constantly – every few months a better open model arrives. The large memory of the MI350P is therefore an investment in the future: the same factory carries DeepSeek V4 Flash or GLM 5.3 today – and tomorrow’s next, larger generation. The hardware stays, the models get better.
Through GEKI, the right configuration is always available – from a single GPU to a full server. Entry already from 1 GPU. Our recommendation (all open models):
| GPUs | Example models | Why it fits well |
|---|---|---|
| 1 | Qwen3.8 27B | compact, a strong model on little hardware – a good entry |
| 2 | DeepSeek V4 Flash | strong agent model, open – a lot of performance for the money |
| 4 | GLM 5.3 Flash | more speed and quality for demanding workflows and more parallel users |
| 8 | GLM 5.3 (full version) | near-frontier quality for the most demanding applications |
You tell us what you want to run – we deliver the right configuration.
Hardware alone is interchangeable and will keep changing. The difference is the software layer on top – inference routing, utilisation, multiple models. It turns cost-efficient hardware into an economical AI factory. That’s exactly why I could choose AMD this time: because our operations deliver the efficiency, not the most expensive GPU.
GEKI operates fully managed AI factories with open models in Austrian and German data centers. The convenience of a hyperscaler (OpenAI-compatible API endpoints), but local, sovereign and affordable. You take care of your application – we take care of everything underneath.
GEKI operates fully managed AI factories with open models in Austrian and German data centers. You choose the location. See the pricing or talk to us.